Module 1: Basics of GPU Hardware
1.1 GPU Structural Composition
• GPU Architecture Analysis (Core, Stream Processors, VRAM, Power Supply Modules)
• PCB Circuit Analysis (Capacitors, Inductors, MOSFETs, VRM)
• Cooling Systems (Air Cooling, Liquid Cooling, Heat Pipes, Thermal Paste)
1.2 Major GPU Brands and Models
• NVIDIA (Tesla, A100, H100, RTX Series)
• AMD (Instinct MI250, Radeon Pro, RX Series)
• Intel (Arc GPU, Data Center GPU)
Module 2: GPU Fault Detection and Diagnosis
2.1 GPU Hardware Fault Analysis
• Black Screen, Artifacts, VRAM Errors
• Power Supply Faults (Burnt MOSFET, VRM Overheating)
• Fan Anomalies (Noise, Stopping)
• Overheating and Throttling (Automatic Throttling, System Reboots)
• VRAM Faults (ECC Errors, VRAM Damage)
2.2 GPU Software Fault Analysis
• Driver Conflicts and Update Failures
• CUDA Computation Errors (GPU Not Recognized, Tensor Core Errors)
• Frequent Crashes (Deep Learning Training / Game Freezes)
• PCIe Connection Issues (GPU Not Detected in Device Manager)
Module 3: GPU Repair Techniques
3.1 Hardware-Level Repair
• PCB Inspection and Reworking (BGA Rework, VRAM Replacement)
• VRM Power Circuit Repair (MOSFET / Inductor Replacement)
• Cooling System Maintenance (Fan Replacement, Thermal Paste, Thermal Pads)
3.2 Software-Level Repair
• GPU Driver Repair (NVIDIA/AMD/Intel Driver Rollback, Reinstallation)
• BIOS Flashing and Repair (VBIOS Backup, Flashing)
• Deep Learning Environment Troubleshooting (CUDA, cuDNN, TensorFlow/PyTorch Compatibility)
Module 4: GPU Maintenance and Optimization
4.1 Data Center GPU Maintenance
• Server GPUs (A100, H100, MI250) Daily Maintenance
• Cleaning and Cooling Management (Air Cooling vs. Liquid Cooling)
• Remote Monitoring Tools (NVIDIA SMI, ROCm System Monitor)
• Power and Temperature Management (Power Consumption Optimization, Energy Saving Mode)
4.2 High-Performance GPU Tuning
• Overclocking and Voltage Optimization (Afterburner, NVIDIA PowerMizer)
• VRAM Optimization (ECC Monitoring, VRAM Temperature Control)
• HPC Computational Task Optimization (Multi-GPU Training, PCIe Passthrough)
Module 1: Intelligent Computing Center Architecture Basics
1.1 Overview of Intelligent Computing Centers
• What is an Intelligent Computing Center ?
• Computing Architectures (CPU, GPU, FPGA, TPU, ASIC)
• Computing Network Architecture (InfiniBand vs. Ethernet vs. RDMA)
• Storage Architecture (HPC File Systems, NVMe, Distributed Storage)
1.2 Computing Resources and Power Pooling
• Physical Computing Resources (GPU Servers, FPGA Acceleration Cards)
• Virtualization and Containerization (Docker, Kubernetes, Singularity)
• GPU Resource Pooling (MIG, Multi-Tenant GPU Resource Management)
• Elastic Computing (Auto Scaling, Serverless Computing)
Module 2: Power Platform Development and Management
2.1 Power Scheduling System
• Task Scheduling Principles (FIFO, Fair Sharing, Gang Scheduling)
• HPC/AI Task Management Tools (SLURM, Kubernetes, Ray)
• GPU/TPU Scheduling Optimization (NVIDIA DCGM, K8s GPU Operator)
2.2 Power Virtualization and Resource Isolation
• GPU Sharing Technologies (vGPU, MIG, Passthrough)
• Automatic Resource Allocation (Helm, Kubernetes Scheduler)
• QoS (Quality of Service) and SLA Management
2.3 Multi-Cluster Power Scheduling
• Cross-Data Center Resource Integration (Federated Learning, Distributed Computing)
• Cloud + On-Premise Hybrid Scheduling (Hybrid Cloud Computing)
• Comparison of Major Scheduling Systems (Kubernetes vs. SLURM vs. Mesos)
Module 3: AI Computing Optimization
3.1 AI Training Task Scheduling Optimization
• PyTorch/TensorFlow Distributed Training Optimization
• Data Preprocessing Pipeline Optimization (TFData, DALI, DataLoader)
• Mixed Precision Training (FP16, BF16, INT8 Computing)
3.2 High-Performance Computing (HPC) Optimization
• Computational Task Optimization (MPI Parallel Computing, OpenMP)
• Parallel Storage Optimization (Lustre, CephFS, BeeGFS)
• InfiniBand High-Speed Network Optimization (RDMA, NVLink)
Module 4: Power Platform Operations and Monitoring
4.1 Computing Resource Monitoring
• GPU/CPU Monitoring (NVIDIA SMI, Prometheus + Grafana)
• Node Health Check (DCGM, K8s Node Problem Detector)
• Task Performance Analysis (NVIDIA Nsight, TensorBoard Profiler)
4.2 Power Efficiency Management
• GPU/CPU Load Balancing
• Low Power Computing Mode (NVIDIA PowerMizer, Dynamic Clocking)
• Green Computing (Energy-Efficient Scheduling, Carbon Emission Optimization)
Module 5: Power Platform Security and Permissions Management
5.1 Data and Computing Security
• AI Task Isolation (Kubernetes RBAC, Multi-Tenant)
• Data Encryption (TPM, Confidential Computing)
• GPU Access Control (GPU Sandbox, vGPU RBAC)
5.2 User Permissions and Billing Management
• Computing Resource Quotas (Quota & Limit Management)
• Task Priority Management (Preemption & Fair Scheduling)
• Computing Billing Statistics (GPU Usage Billing, Cost Optimization)
Module 6: Cloud Intelligent Computing Platform Architecture and Practice
6.1 Public Cloud Power Platform Setup
• AWS SageMaker, GCP AI Platform, Azure ML
• Kubernetes + Kubeflow for AI Task Management
6.2 Self-Built Intelligent Computing Center Case Studies
• Enterprise AI Power Center Construction (Nova Tech, Alibaba Cloud PAIS, Baidu AI Cloud)
• University AI Computing Platforms (Tsinghua Intelligent Computing Center, Berkeley HPC Center)
• Government and Research Intelligent Computing Platforms (China National Supercomputing Center, NASA Ames HPC)
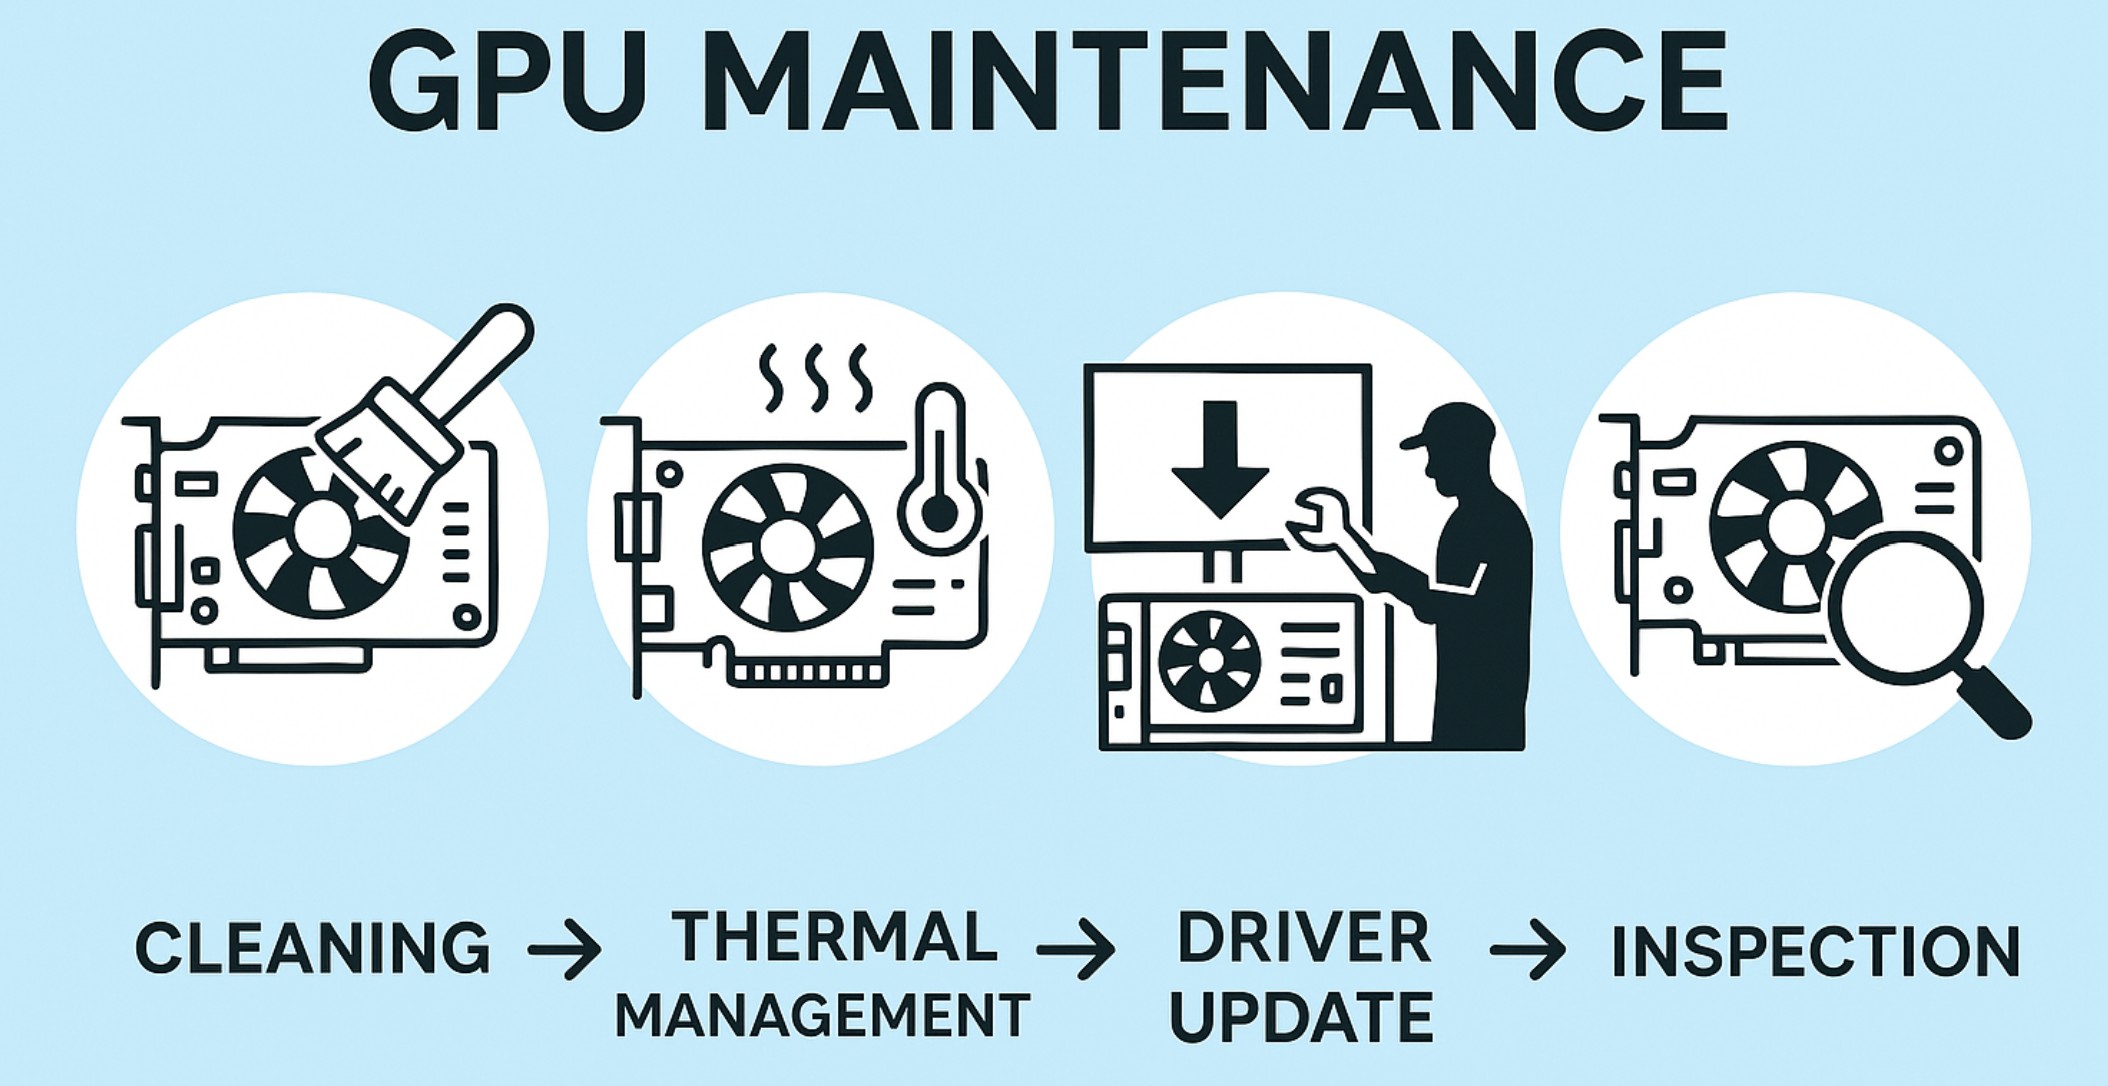
GPU Maintenance